import pandas as pd
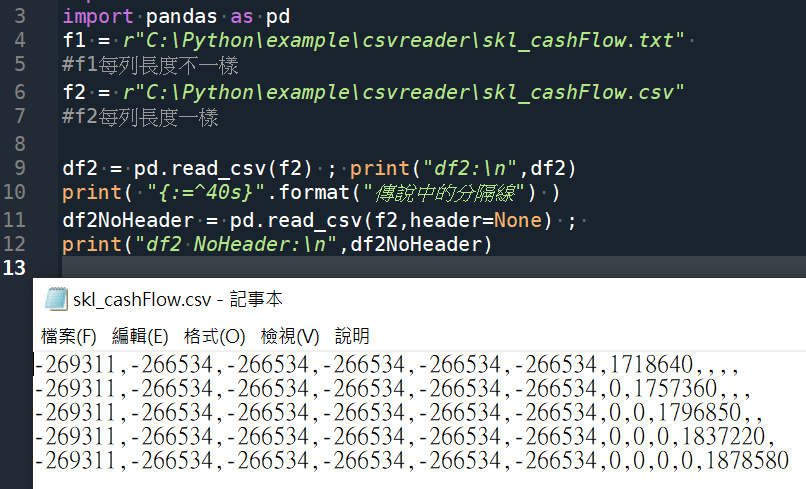
f1 = r”C:\Python\example\csvreader\skl_cashFlow.txt”
#f1每列長度不一樣
f2 = r”C:\Python\example\csvreader\skl_cashFlow.csv”
#f2每列長度一樣
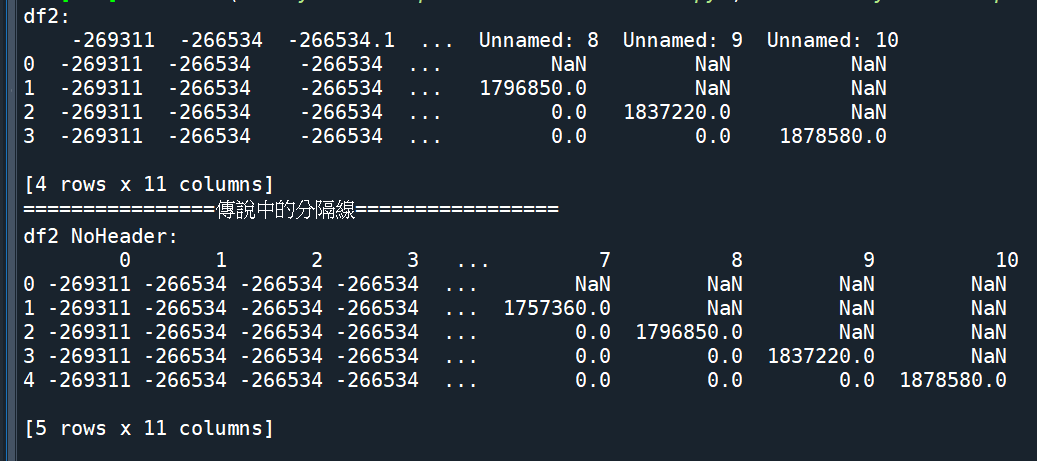
df2 = pd.read_csv(f2) ; print(“df2:\n”,df2)
#誤把第一列的資料當欄標籤
print( “{:=^40s}”.format(“傳說中的分隔線”) )
df2NoHeader = pd.read_csv(f2,header=None) ;
print(“df2 NoHeader:\n”,df2NoHeader)
#自動補0~10為欄標籤
輸出結果:
![Python 如何用pandas.Series.nsmallest() 找到n個與target差距最小的index?再從中找到距離idxmax最近的index?避免誤抓sidelobes的index? targetIdx = (serMean-target_value).abs().nsmallest(n).index.tolist() ;Series切片: .loc[標籤名1:標籤名2] (會含標籤名2) ; .iloc[位置1:位置2] (不含位置2) Python 如何用pandas.Series.nsmallest() 找到n個與target差距最小的index?再從中找到距離idxmax最近的index?避免誤抓sidelobes的index? targetIdx = (serMean-target_value).abs().nsmallest(n).index.tolist() ;Series切片: .loc[標籤名1:標籤名2] (會含標籤名2) ; .iloc[位置1:位置2] (不含位置2)](https://i1.wp.com/savingking.com.tw/wp-content/uploads/2023/02/20230222082954_53.png?quality=90&zoom=2&ssl=1&resize=350%2C233)


![Python: pandas.Series如何只保留str,去除重複值?#isinstance(x:Any, str) -> bool #.drop_duplicates() #Series.apply( function )逐元素應用function運算 #DataFrame.apply( function )逐Series應用function運算 .drop_duplicates() 跟.unique()有何差別? df.drop_duplicates() 等效於 df[~df.duplicated()] Python: pandas.Series如何只保留str,去除重複值?#isinstance(x:Any, str) -> bool #.drop_duplicates() #Series.apply( function )逐元素應用function運算 #DataFrame.apply( function )逐Series應用function運算 .drop_duplicates() 跟.unique()有何差別? df.drop_duplicates() 等效於 df[~df.duplicated()]](https://i0.wp.com/savingking.com.tw/wp-content/uploads/2024/11/20241123194900_0_5218de.png?quality=90&zoom=2&ssl=1&resize=350%2C233)
![Python:如何使用 PyMuPDF (import fitz ) 提取 PDF 文本區塊並存儲為 DataFrame ; text: List[ Tuple[float|str|int] ] = page.get_text(“blocks”) Python:如何使用 PyMuPDF (import fitz ) 提取 PDF 文本區塊並存儲為 DataFrame ; text: List[ Tuple[float|str|int] ] = page.get_text(“blocks”)](https://i2.wp.com/savingking.com.tw/wp-content/uploads/2025/03/20250320084417_0_7783bd.png?quality=90&zoom=2&ssl=1&resize=350%2C233)


近期留言